
Apache 2.0, weights free on Hugging Face, no terms to accept. The catch is size: at 14 billion parameters this is a data-centre GPU rather than a workstation card, and the vendor's own speed figures assume an H100. In your browser it runs on CNAPS Studio, included in the basic plan, and that is the only route most people will take.
What it is for is length. Most video models stop somewhere between five and ten seconds, or slow to a crawl past that, because quality drifts once a clip runs long. Helios Base generates up to about sixty seconds in one go, from a text description, a starting image, or an existing clip, and it does it by building the video in 33-frame chunks that each continue from the last rather than by generating the whole thing at once.
The cost is time and resolution. The studio card is honest about it: expect three to ten minutes for a clip, so the vendor's real-time claim describes ideal hardware rather than your afternoon. And the frames themselves are small, with the largest preset 768 pixels on its longest side. Two Helios variants sit in the CNAPS Studio catalog, and this is the one to reach for when quality matters more than turnaround.
What it actually is
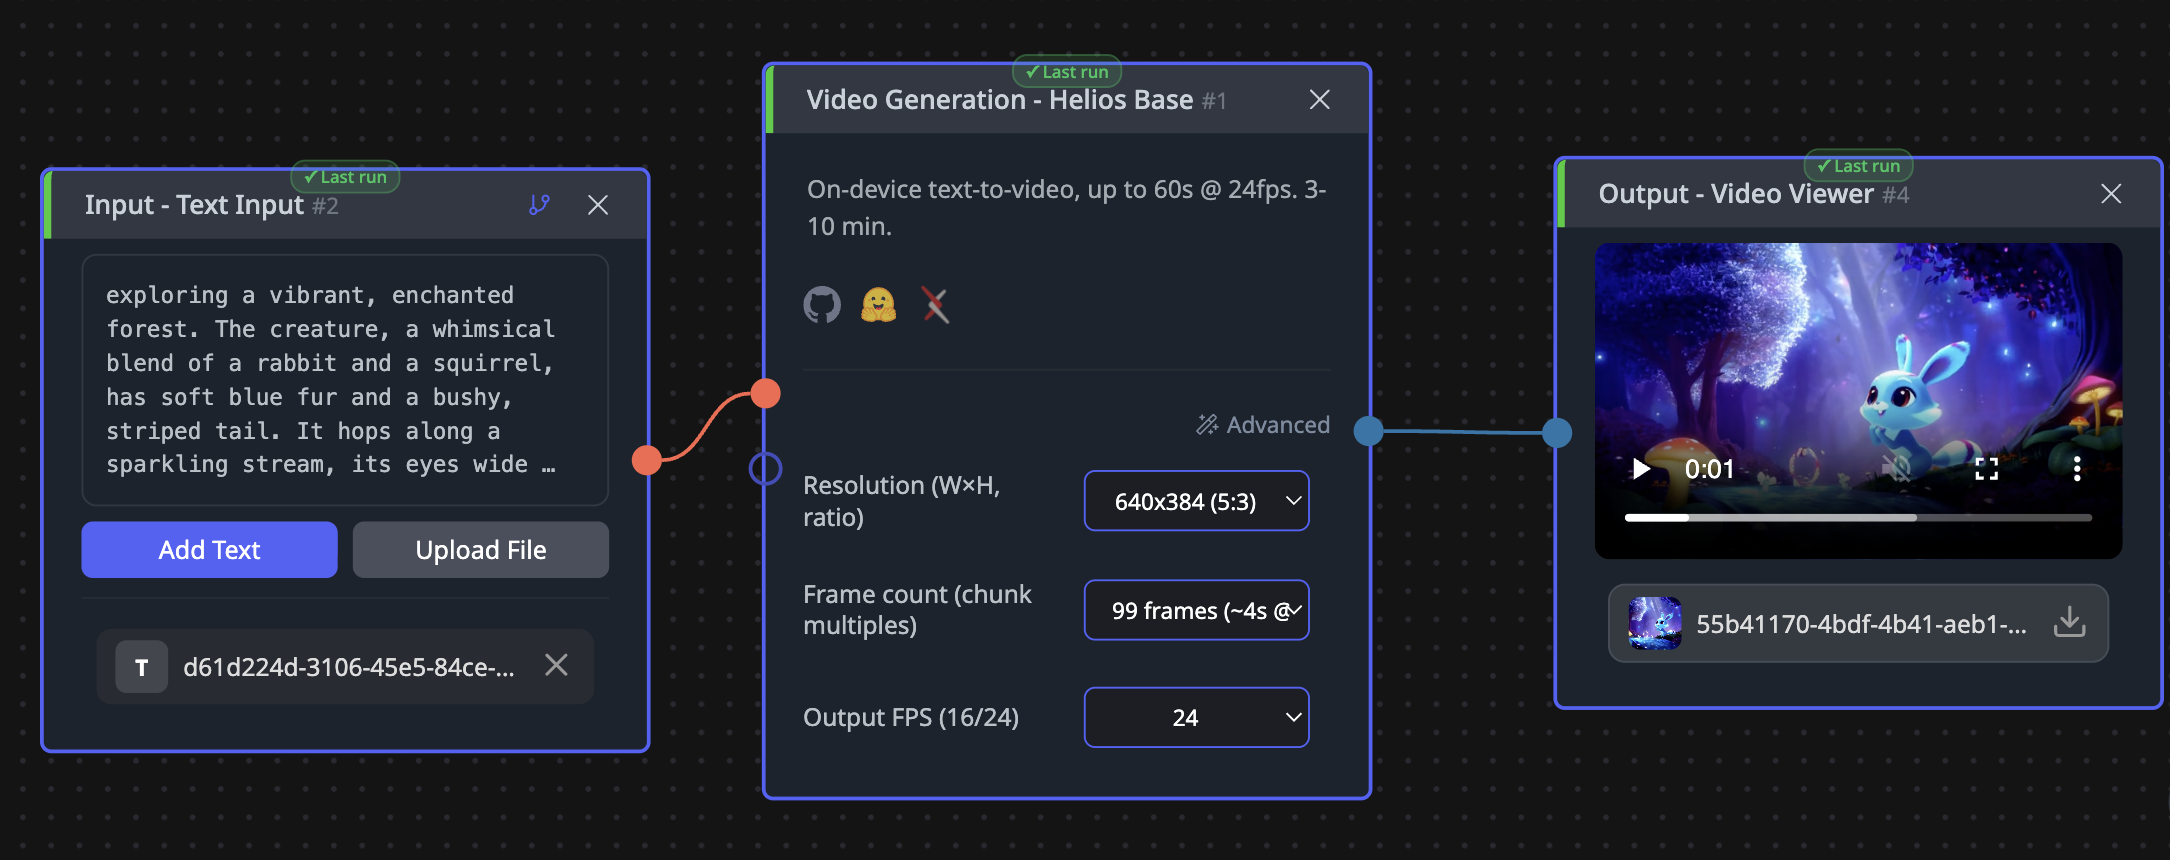
An autoregressive diffusion model that writes video a chunk at a time. Each chunk is 33 frames, and each one is conditioned on what came before, which is why the frame-count dropdown only offers multiples: 99 frames is three chunks and about four seconds at 24 frames per second, 1,452 frames is the top of the list at roughly sixty seconds.
Three inputs work. Text alone describes a scene from nothing. An image plus a description animates a still. An existing clip plus a description transforms or extends it. Our own documentation adds a caveat the model card does not: the image and video modes tend to be less consistent than text, because training concentrated on text.
Resolution is a dropdown of eleven presets rather than a free field, across landscape, square and portrait, defaulting to 640 by 384. Output frame rate is 16 or 24. The setting that decides quality is diffusion steps, 20 to 60 with a default of 50, meaning how many passes the model makes over each chunk. That slider is the whole quality-for-speed trade here.
What is published, and what is not
There is no benchmark table. No quality score, no evaluation against other video models, nothing to rank. For a field where video quality comparisons are contested anyway, that absence is worth naming rather than papering over.
What is published is the engineering. It generates at 19.5 frames per second on a single H100, faster than the 24 frames per second the video plays back at, and around 10 on an Ascend NPU. It reaches sixty seconds on one GPU rather than a cluster, without the usual bag of tricks for holding long generations together. It is a fine-tune of an existing 14-billion-parameter video model rather than a fresh design.
All of that is vendor-reported, from PKU-YuanGroup's own model card, with no third-party evaluation. Adoption is thin at 592 downloads in the last month, which for a model this size mostly reflects how few people have hardware to run it. Which leaves your own eyes as the evidence, on your own prompts.
How it compares to the other video generators here
None of the video generation models in the catalog publishes comparable quality scores, so any table of numbers here would be a table of specifications rather than a ranking. What separates them is clip length, control and speed.
Reach for Helios Base when the clip needs to run longer than ten seconds and you can wait for it. Reach for Helios Distilled when you want the same length faster and will accept less detail, since it drops the diffusion-step slider for a fixed fast schedule and fixes the resolution. Reach for Wan2.2 TI2V 5B when you want a short clip at higher resolution from a much smaller model. Reach for Cosmos3 Nano or MiniMax H3 (Ref2VA) when their particular input shapes fit what you have.
What to chain it with
Input is a text description, optionally an image or a clip. Output is an MP4. That output being a real video file rather than a frame sequence is what decides the chains.
Two are worth building. Because the frames are small, upscaling is the natural next step: send the clip to SparkVSR or FlashVSR-v1.1 and the sixty seconds you generated at 640 by 384 becomes something you can put on a large screen. And for a vertical cut, Subject Follow (9:16) will track a subject through the generated clip and hand back a 1080 by 1920 version without manual cropping.
Open Helios Base in CNAPS Studio, generate the same prompt at 20 diffusion steps and at 50, and decide whether the extra detail is worth the extra minutes before you commit to a batch.
Sources
- huggingface.co/BestWishYsh/Helios-Base for the Apache 2.0 license, the 14 billion parameter count, the 19.5 frames per second figure and its hardware, the Ascend NPU figure, the 33-frame chunking, the sixty-second maximum, the three input modes, the absence of any benchmark table, and the monthly download count.
- docs.cnaps.ai/ai-model-hub for the CNAPS Studio resolution presets, the frame-count list, the output frame rates, the diffusion step range, the expected runtime, and the note about image and video modes being less consistent than text.