LTX-2.5 Audio-to-Video: a talking video from one still and one voice, and where to run it
Community license, weights free to download, commercial use free for companies under USD 10 million in yearly revenue. It uses the same LTX-2.5 weights as the text-to-video model, about 71GB read for every clip, run through a two-stage audio-to-video pipeline in Lightricks' repository; no memory figure is published. In your browser it runs on cnaps studio, included in the basic plan.
It turns one still and one voice recording into a talking video. The voice drives the lips, the face and the gestures, and the original audio is kept exactly as you supplied it, so a recorded narrator, a designed voice or a client's own take comes out untouched. The clip is as long as the voice.
The cost is time. In the studio a 13-second voice takes four to five minutes and a 29-second one about fifteen, and a single clip tops out at 30 seconds. Eight video generation models sit in the cnaps studio catalog, and this is the one for animating a portrait to a voice you already have.
What it actually is
The audio-to-video mode of Lightricks' 22-billion-parameter LTX-2.5. The first stage generates the video at half resolution while the audio stays frozen as a condition, and the second doubles the resolution and refines it with a distilled adapter. The waveform itself is never regenerated, which is why the voice comes out unchanged.
A detail worth knowing: the model keeps roughly the first half second of video close to the still image. The studio adds a short silent lead-in before the voice and trims it afterwards, so the lips are already moving on the first word.
In cnaps studio you connect an image, a voice of 0.5 to 30 seconds, and optional text describing the motion or scene. The canvas defaults to auto, which picks the closest of 768 by 1344, 1344 by 768 and 1024 by 1024 and centre-crops the image; a pad option keeps the whole picture instead. Steps run from 10 to 60, default 30, at about five seconds each.

Try LTX-2.5 Audio-to-Video in cnaps studio →
One photo and one voice line in, a talking clip out. Turn the sound on.
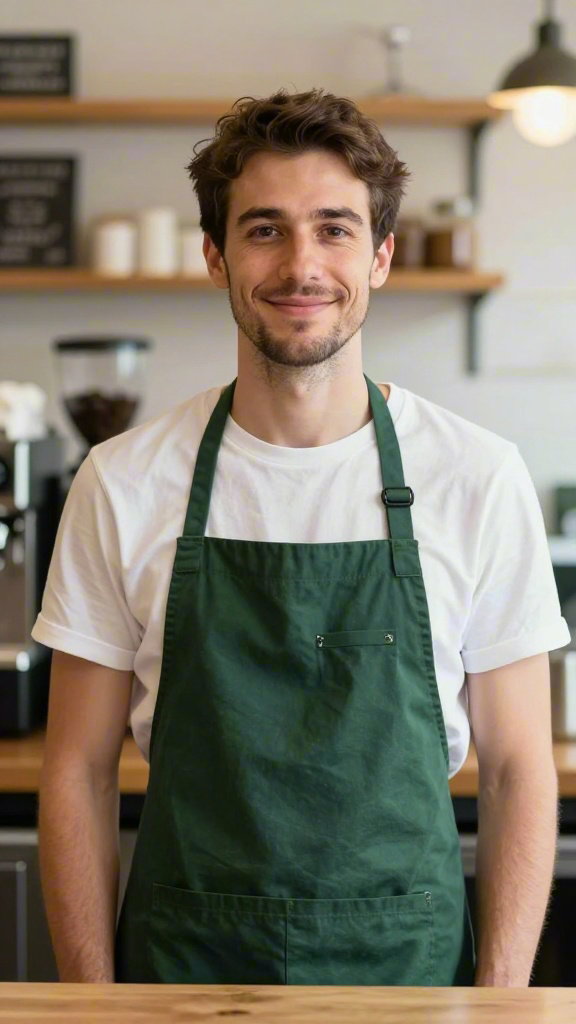
Image (first frame) — made with Z-Image-Turbo, 576×1024
Result
Voice — Text to Speech (Qwen3 Voice Design), described as "a friendly man in his early thirties with a natural American accent, warm and upbeat":
"Hi there! Fresh coffee's ready. The beans came in this morning, so grab a cup before they run out."
Output size auto (768×1344) · steps 30 · warm-up 0.8 s · motion prompt: talks to the camera, natural head movement, static camera, "no text, no subtitles".
Tip from this test: on the first seed the model drew garbled subtitle-like words over the apron, even with "no subtitles" in the prompt. A different seed came out clean. If you see text in the frame, re-run with another seed.
The published numbers
Lightricks has published no quality scores for audio-to-video in 2.5. The numbers that matter in practice are the studio's own timings, which grow with both the voice length and the step count.
The step default of 30 matches the checkpoint's own default in Lightricks' pipeline, so lowering it trades detail for speed rather than fixing anything. Only the first stage uses the step count; the refining stage always runs its short distilled schedule.
Plan around the wait. A minute of narration means two or three separate clips of a few minutes each.
How it compares to the other talking-video models here
These four share no published test, so the table maps what you start from. The first question is whether you hold a still, existing footage, or only a script.
Reach for LTX-2.5 Audio-to-Video with a portrait and a finished voice. Reach for LatentSync 1.6 when the footage already exists, MiniMax H3 to build a scene from references, and LTX-2.5 when the model can write the speech too.
What to chain it with
A picture and a voice in, a talking clip out, so it sits at the point where the two meet.
The example above is the standard chain: Z-Image-Turbo designs the presenter, Qwen3 Voice Design writes the voice from a one-line description, and this model joins them. Swap in Qwen3-TTS for a preset voice, and split a long script into parts under 30 seconds before the voice step.
Open LTX-2.5 Audio-to-Video in cnaps studio, run a 10-second line at the default settings, and watch the first word to see the lead-in at work.
FAQ
What does LTX-2.5 Audio-to-Video need to run locally?
The LTX-2.5 weights, about 71GB, and Lightricks' two-stage audio-to-video pipeline, which needs Python 3.12 and CUDA 12.7 on a large GPU. No memory figure is published, and 8-bit weights with CPU offload help smaller cards. In cnaps studio it runs in the browser, included in the basic plan.
What kind of image works best?
One person, facing the camera, on a plain background. A flat green backdrop makes the result easy to composite later. If the picture's shape differs from the canvas, the default crop can cut the head or shoulders, so switch the fit setting to pad, which extends the background instead of cropping.
Will the model change my audio?
No. The voice conditions the video but is never regenerated, and the original file is muxed into the result unchanged. That keeps a recorded or designed voice exactly as approved. Do any music or loudness work on the finished clip, since the output timing always follows the voice you supplied.
