
BiRefNet — Segmentation AI Model
BiRefNet removes backgrounds by isolating the single most salient subject, holding edges clean through hair, fur and translucent fabric where most cutout tools smear. One subject per pass, one to three seconds.
Demo
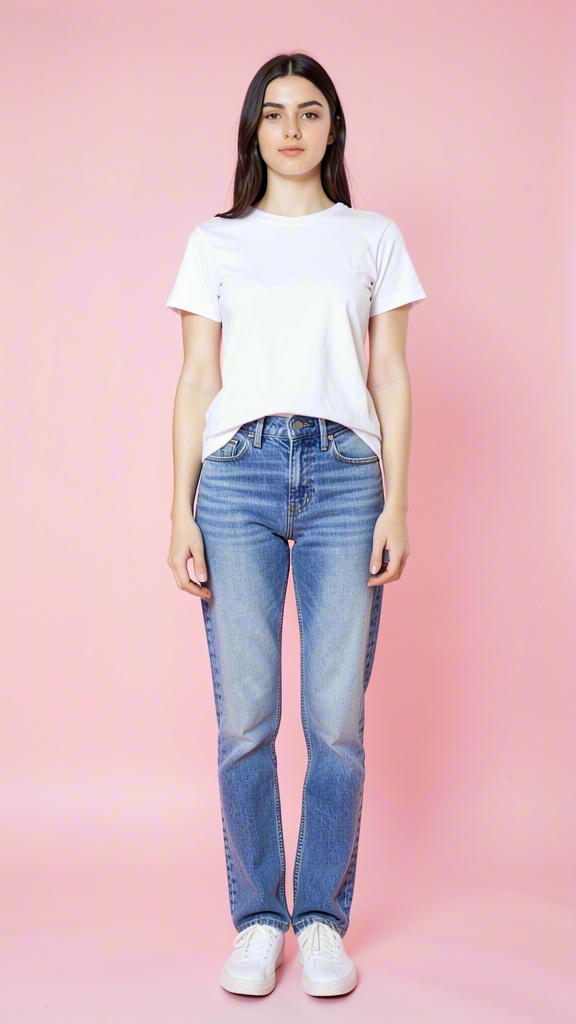
Input — a photograph with a background
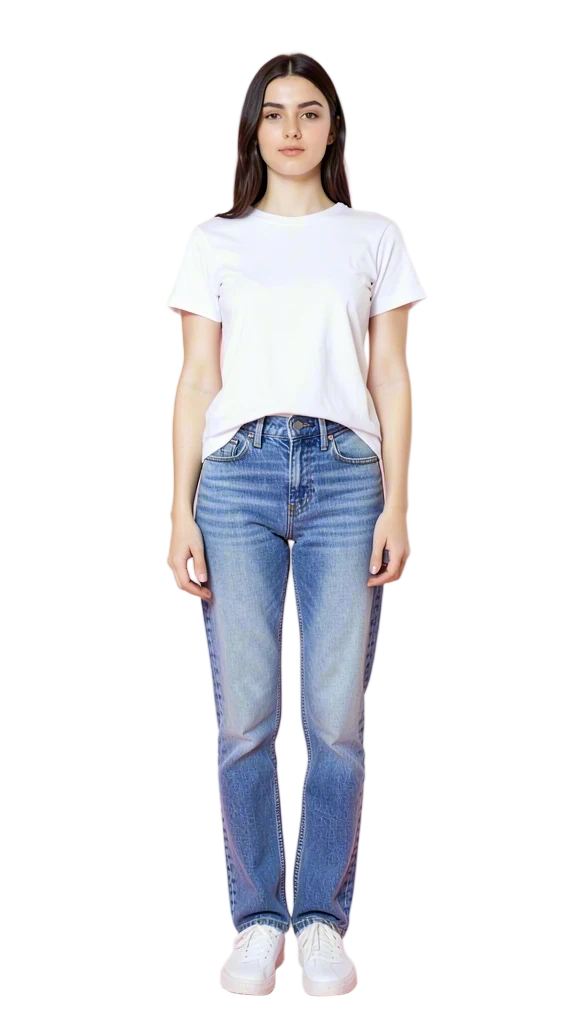
Output — the subject cut out, background transparent
What it does
BiRefNet looks at a photo, figures out what the main subject is, and creates a precise outline around it so you can lift that subject off its background. Think of it as an automatic version of the “remove background” button in photo editing tools, but with far better quality.
It excels at the edges most tools get wrong: individual strands of hair, the gaps between tree branches, lace, fur, mesh and other fine details. It works at high resolution, which means the cutouts stay sharp and clean even on large images.
When to use it
- Clean background removal — produces transparent cutouts that look professionally edited, not roughly traced
- Tricky edges and fine details — handles hair, fur, leaves and other outlines that simpler tools mangle
- Automatic subject detection — finds the main subject on its own, with no clicking or describing required
- Hidden or camouflaged subjects — can still outline subjects that blend into their background
- Product photos — generates clean, transparent product images suitable for e-commerce and marketing
Details
- CategorySegmentation
- Year2024
- LicenseMIT
Compliance & Provenance
- ProviderOpen-source · Specialized
- EU AI Act RiskMinimal Risk
- Art. 50 TransparencyNot applicable
Inputs & Outputs
- ImageInputimage
Source image — BiRefNet detects the most salient subject (foreground)
- ImageOutputimage
Segmentation overlay (subject in color, background black); with extract_foreground enabled, a transparent-background RGBA cutout of the subject instead
- TextOutputstring
Segment metadata — connect to Masking-Image-Masker-By-Class with class 'subject' or 'object_0' to obtain a binary mask
Parameters
- versionstringdefault Generaloptions: General, HR, Lite-2K
Model variant
Which BiRefNet variant to use. 'General' (default) is the standard 1024² SwinL choice — pick this unless you have a specific reason. 'HR' uses the same SwinL backbone at 2048² input — best when the source image is large (2K+) or contains many fine details like hair, fur, or plant leaves where boundary precision matters most. 'Lite-2K' uses a lighter SwinT backbone at 2560×1440 input — faster and ~60% smaller VRAM footprint, suitable when latency or resource cost matters more than absolute edge precision.
- extract_foregroundbooleandefault false
Output transparent-background foreground cutout (RGBA)
When true, the image output becomes a transparent-background RGBA cutout (PNG) of the detected subject instead of the colored overlay. Edge pixel colors are decontaminated with fast foreground estimation, so no background color bleeds into fine boundaries like hair — unlike the Masker-By-Class + Image-Multiply chain, which keeps mixed foreground/background colors in edge pixels. Use this for background removal / cutout tasks; the RGBA output is final and must not be wired into Masking-Image-Masker-By-Class (that node expects the colored overlay — keep this false when a downstream node needs a binary mask). The text metadata output is unaffected either way.
- background_colorstringdefault transparentadvanced
Cutout background: transparent, or a hex colour like #00B140.
Only with extract_foreground=true. 'transparent' (default) keeps the RGBA cutout. A hex colour (#RRGGBB) composites the cutout onto that solid colour and outputs RGB - e.g. #00B140 turns an ordinary portrait into a green-screen presenter for a talking-head model (LTX-2.5 Audio-to-Video takes RGB only) followed by Chroma Compose. Any other value fails with AI.INVALID_VALUE. Ignored in overlay mode.
Tags
Alternatives in Segmentation
- RF-DETR Seg Medium (Scene)
Real-time instance segmentation on 80 COCO classes (RF-DETR Seg Medium).
- SAM2 (Scene)
Segment every object in an image (no labels needed). 10-30s.
- SAM3 (Scene)
Language-prompted segmentation (e.g. "person", "red car"). 10-30s/class.
- SAM3.1 (Scene)
Language-prompted segmentation — SAM 3.1 Object Multiplex with improved accuracy over SAM3. 10-30s/class.