
Annotator-DepthAnything — Annotation AI Model
Depth Anything V1 Large estimates depth from one photo, no stereo rig — near reads white, far reads black, and fine structure like hair or foliage survives. Feeds ControlNet Union depth mode. 1.4GB VRAM, sub-second.
Demo
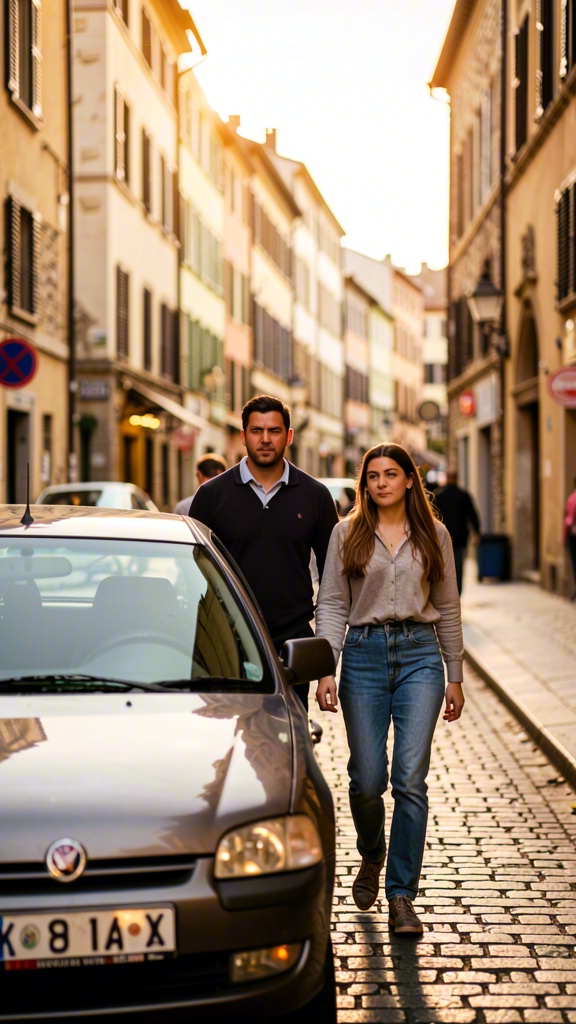
Input — a street photograph
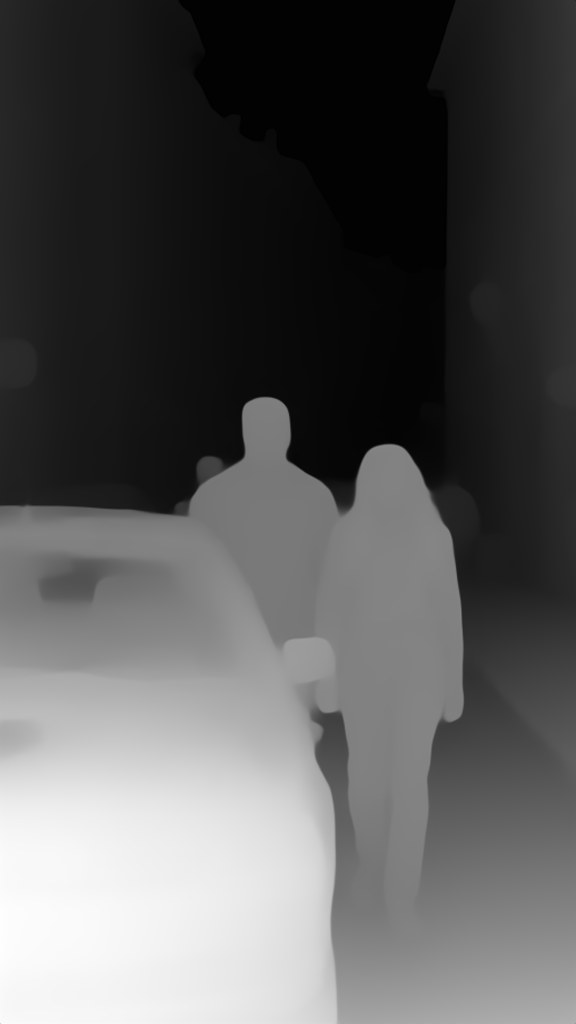
Output — the depth map: bright is near, dark is far
What it does
Depth Anything Annotator estimates how far away every pixel of a photo is from the camera, and outputs that as a grayscale image — bright pixels are close to the camera, dark pixels are far away. It does this from a single regular photo, with no stereo cameras, depth sensors or multiple viewpoints required.
Under the hood it uses Depth Anything V1 (Large), a depth model trained on roughly 62 million images. The output is exactly the format ControlNet-Union expects in its depth mode, making this the standard preprocessor for any image-generation flow that uses depth as structural guidance.
When to use it
- ControlNet-Union depth conditioning — generates the exact grayscale depth image depth-guided generation needs
- Preserving fine detail — excels at fragile structures like hair, foliage, branches and mesh, where simpler models smear
- No special hardware — works from any normal photo, with no depth sensor or stereo rig
- Style transfer with geometry preservation — restyle a scene while keeping its 3D layout intact
- Background separation — use the depth map as a soft mask for foreground and background editing
Details
- CategoryAnnotation
- Year2024
- LicenseApache-2.0
Compliance & Provenance
- ProviderOpen-source · Specialized
- EU AI Act RiskMinimal Risk
- Art. 50 TransparencyNot applicable
Inputs & Outputs
- ImageInputimage
Source image for depth estimation. Works on any natural scene — indoors, outdoors, portraits, objects. RGB accepted; alpha channel is ignored.
- Depth MapOutputimage
Grayscale depth map at the same resolution as the input. White pixels are closest to the camera, black pixels are farthest. Feed into ControlNet-XL-Union (depth mode) for depth-guided image generation.
Tags
Alternatives in Image Control
- ControlNet XL Canny
Guided SDXL image generation from a Canny edge map + text prompt. Sharper structural adherence than Union. Outputs up to 1024×1024.
- ControlNet XL Union
Guided SDXL image generation from a control image + text prompt. One model, 6 modes: canny, depth, openpose, hed, normal, segment. Outputs up to 1024×1024.